

Data orchestration services for complex enterprise environments
The same customer exists in three systems, recorded three ways, and nothing says which is right. Our data orchestration services find what each system holds, agree what correct looks like, and keep clean records flowing between them, on your own infrastructure.
We work with clients and partners across the globe.


Definition
What is data orchestration?
Data orchestration is the work of moving, cleaning and matching data across separate systems so that every application receives the same record the same way. It is not a data warehouse and it is not a workflow builder. It is the layer underneath both: discovering what each system holds, agreeing what a correct record looks like, validating and mapping records as they move, and keeping the flows running when a system changes.
It matters because every application is correct on its own terms and wrong about the others. Reports disagree, people re-key, and anything built on top, automation or AI, inherits the mess. Fix the layer once and everything above it improves.
The problem
The data problems underneath every system you run
Each application is correct on its own terms. The failures the business notices sit a layer above where the fault actually is.
- The same customer exists in three systems, recorded three different ways.
- Fields that mean the same thing carry different names and formats in each application.
- Two systems hold the same record and nothing says which one is right.
- People re-key and correct the same records by hand every week.
- Two reports pull the same figure and disagree, so neither gets used.
- AI built on the data fails once it leaves the demo.
What we do
What our data orchestration services cover
Five capabilities, outcome first. Each one applies to a situation most estates recognise.
-
Discovery and data cataloguing
Request a data auditWhat data exists across the estate and where it lives, read from each system’s own API. For businesses that cannot answer that question today.
-
Data cleansing and standardisation
Request a data auditRecords validated and mapped so every system receives them the same way. The step most integration projects skip, and the reason they fail later.
-
Connecting systems without APIs
Request a data auditApplications with nothing to integrate through, brought into scope.
-
No code flows your team can change
Request a data auditFlows built so your own people can alter them without a developer, on a canvas rather than in code.
-
Keeping connections working
Request a data auditVendor version changes handled at one connection rather than by rebuilding the integration each time.
The platform
L1nks
The platform that connects systems and cleans the data
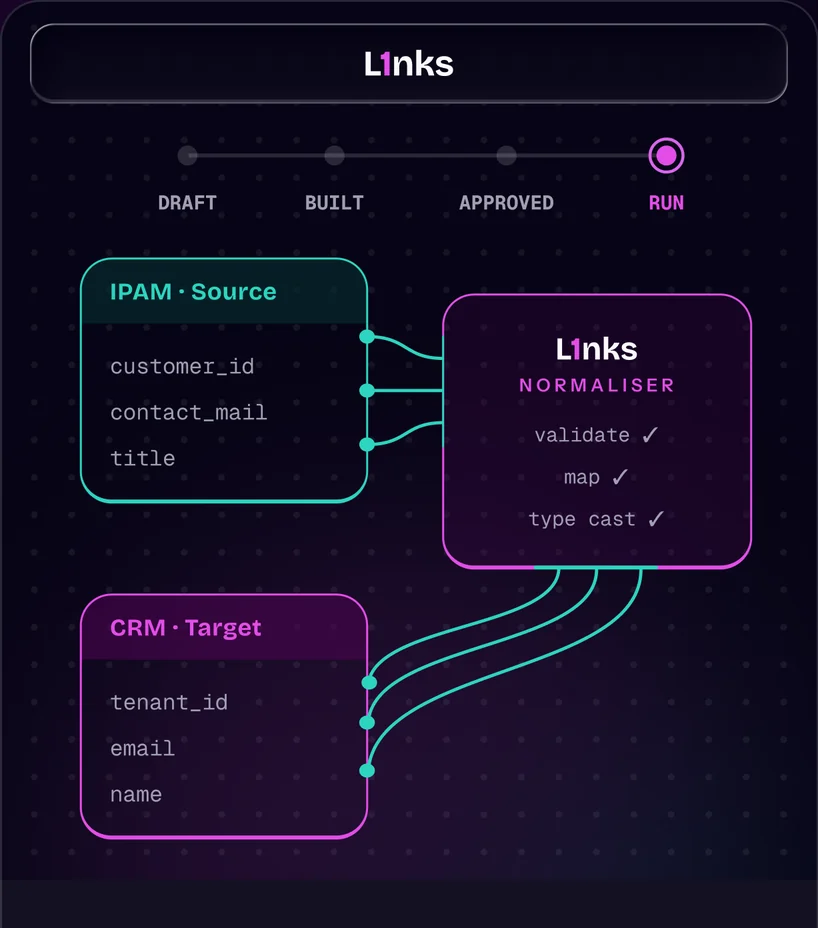
L1nks is Elev8’s own data fabric and orchestration layer. It reads every system’s fields and data shapes from its API, catalogues what each one holds and the names it uses, and validates, maps and type casts records while they move, so what arrives is already correct.
Each system connects once, never to another system, so the sixtieth costs what the tenth did. Flows run on demand or on a schedule, and a vendor’s version change is absorbed at one connection.
The engagement
How a data orchestration engagement works with Elev8
Five steps, and what you hold at the end of each. This is the engagement, not the platform’s internal sequence.
-
Audit
The systems in scope and what data each one holds. You get a catalogue where before there was a guess.
-
Mapping
How records match across systems and what correct looks like per field, agreed with the people who own each one before anything is built.
-
Build and test
Flows built and run against real data before going live, with the receiving systems checked for what arrives.
-
Governance
Who can reach what, granted by role.
-
Handover
Your team able to run and change flows themselves, on the no code canvas.
Why Elev8
Why businesses choose to work with Elev8
The platform is ours, so a fix does not wait on another vendor.
-
The orchestration platform is ours
L1nks is built and supported by Elev8, so a fix does not wait on a vendor and a feature you need can be built.
-
Each system connects once
A new system adds one connection to the fabric, not one per existing system, so cost grows in a line rather than a curve.
-
Cleansing is the first step, not the last
Records are validated and mapped in transit, so the receiving system is spared the reconciliation that normally follows.
-
Your team can change the flows
They are built on a no code canvas and handed over, not locked behind a developer.
-
Version changes are handled at one connection
A connected system’s update is absorbed where it connects to the fabric, so every flow through it keeps running.
-
Worth doing with no AI project planned
Cleaner reports, less re-keying and one version of each record pay back on their own. AI is a later option, not the reason.
Sectors
Industries we serve
Every sector has its own records, systems and ways of working. We learn yours first, then build AI and software that fit the way your teams already operate.
Telecom and ISPs
App and network experience monitoring, and data integration across operator systems.
Learn more, Telecom and ISPsConstruction
Permit automation, faster responses to tenders, analytics and talk to your documents.
Learn more, ConstructionFinancial services
Liveness checks, KYC, identity verification and fraud prevention.
Learn more, Financial servicesOther services
AI, automation and infrastructure
Whether it is AI, custom software, CRM/ERP rollout or the cloud and infrastructure to run it, we scope it, build it and support it after going live.
-
Learn more , Custom AI development
Custom AI development
AI that understands your business, built on your own data and shaped around the way your teams work.
-
Learn more , Custom and automated software development
Custom and automated software development
Business software, internal tools, workflow automation and legacy replacement.
-
Learn more , AI integration and deployment
AI integration and deployment
AI and agents deployed into the systems you already run, and connected to your data.
-
Learn more , AI strategy and consulting
AI strategy and consulting
Readiness, roadmap, use case prioritisation and governance, from AI experts.
-
Learn more , Data strategy consulting
Data strategy consulting
Deciding what data to keep, who owns it and what to fix first, then delivering it in that order.
-
Learn more , AI cloud and security
AI cloud and security
Private AI environments, on premises, in your cloud or air gapped, with your data kept in bounds.
-
Learn more , Odoo ERP and CRM
Odoo ERP and CRM
Odoo fitted to your process: apps, custom modules, integration and data migration.
In their words
What our customers say about us
Don’t just take our word for it, hear it from our clients.
-
- Manufacturing
Donut Safety Systems
Delivered an LMS and a custom CRM to manage & track trainings, certifications, manufacturing process, marketing and sales.
Read moreElev8 has been a fantastic partner in supporting the creation, maintenance of our Learning Management System. What really sets them apart is how collaborative they are, they take the time to understand our business and tailor bespoke solutions rather than offering a one-size-fits-all approach. Their compliance guidance has also been invaluable, giving us confidence that our system and reporting meet the standards we require.
Working with Elev8 has made a real difference to how we manage systems across our business. We wouldn’t hesitate to recommend them to any organisation looking for a systems provider that genuinely acts as a partner rather than just a supplier. Thanks again for everything the team does for us, it’s a pleasure working with Elev8.
Insights from our team
Notes on data that disagrees with itself, and what to fix first.
-
Data governance that survives an audit
What data is held, what for, and who governs it, written down in a form a regulator will accept.
-
AI strategy for regulated industries
Where AI is worth using in a regulated business, where it is not, and how to tell the difference before you spend.
-
Retention policies for training data
How long to keep the data a model was trained on, who decides, and how to delete it without losing the audit trail.
Common questions
Data orchestration questions, answered plainly
Everything you need to know about working with Elev8.
What is the significance of data fabric and data orchestration?
A data fabric is the connected layer that knows what every system holds and how records relate. Data orchestration is the work that runs on it: moving, cleaning and matching records between systems. Together they mean each application connects once and receives correct data, instead of every pair being wired by hand.
How does data orchestration work?
Discovery finds the systems and fields, a catalogue records what each holds and the names it uses, and mapping agrees what a correct record looks like per field. Flows then validate, map and type cast records in transit, on demand or on a schedule, and a change in one system is absorbed at its single connection.
Does Elev8 have the tools to handle data orchestration?
Yes. L1nks is our own data fabric and orchestration platform, built from the same problem on client work and in production today. Because we own it, a fix does not wait on a vendor’s release cycle, and the flows are handed to your team on a no code canvas.
What does a project like this involve for our team?
Mostly decisions rather than effort. The people who own each system agree what correct looks like per field at the mapping step, and someone checks what arrives during build and test. Nobody has to write code. At handover your team takes over the flows, and we agree what support covers with you.
Do we have to replace the systems and software we already use?
No. Orchestration connects the systems you have and leaves each one as the system of record for what it holds. Replacing a system becomes a decision you can make on its own merits later, because the flows around it are already in place.
How disruptive is it to operations while the work is happening?
Very little. Discovery and cataloguing read from systems without changing them, flows are built and tested against real data before going live, and the first live flows run alongside the manual process until they have proved themselves. Nothing is switched off until the new route has been checked.
Is this worth doing if we have no AI project planned?
Yes. One version of each record, reports that agree, and an end to weekly re-keying pay back on their own. If an AI project comes later it lands on data it can use, but that is an option the work leaves open, not the reason to do it.
Let's fix your data layer problems
Tell us which systems disagree with each other. A data audit is a good first step, and it tells you what to fix first.